AI News · ai software
Why Everyone Is Talking About BlueLM-GUI, the Mobile AI Outperforming Closed Models
A technical report authored by 43 researchers introduces BlueLM-GUI, a 35B-A3B parameter mobile AI agent trained directly on physical smartphones that surpassed top proprietary models on standardized mobile benchmarks.
What happened
- On September 11, 2026, Tong Ye and 42 co-researchers (43 authors in total) published the technical report for BlueLM-GUI on arXiv (arXiv:2609.12394).
- BlueLM-GUI is built at a 35B-A3B parameter scale, operating graphical user interface (GUI) tasks directly on smartphone screens.
- The model scored 87.4 points on the MobileGUI-VBench benchmark, outperforming the leading closed proprietary model by 5.1 points.
- It registered 84.9 points on the AndroidWorld benchmark, ranking first among all open-source models evaluated.
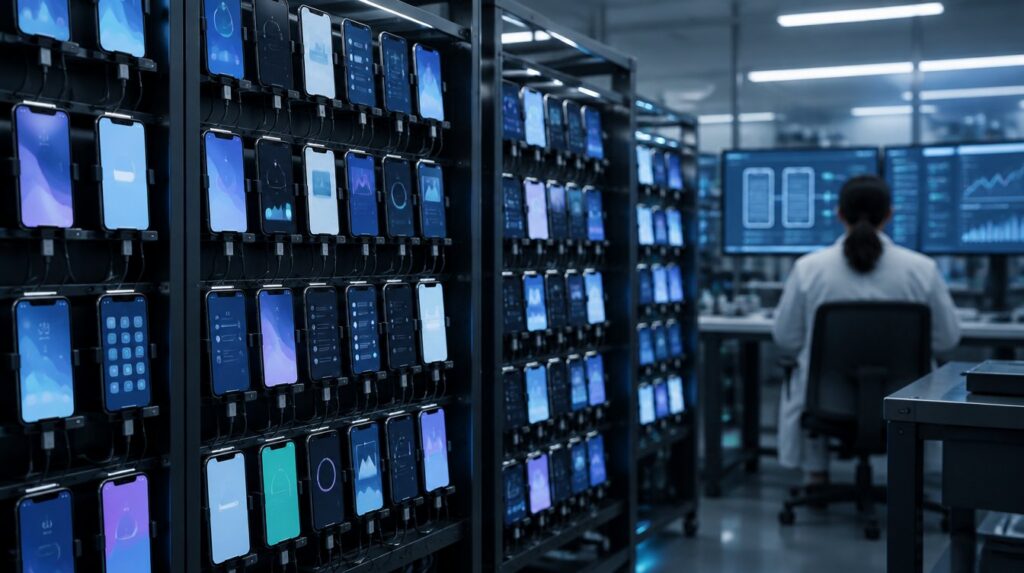
- Training relied on reinforcement learning across hundreds of physical smartphones under the core rule "Every Rollout Is Real."
Why it matters
Mobile graphical user interface (GUI) agents are software systems engineered to visually recognize on-screen components and execute actions directly on mobile operating systems, allowing users to automate multi-step device workflows.
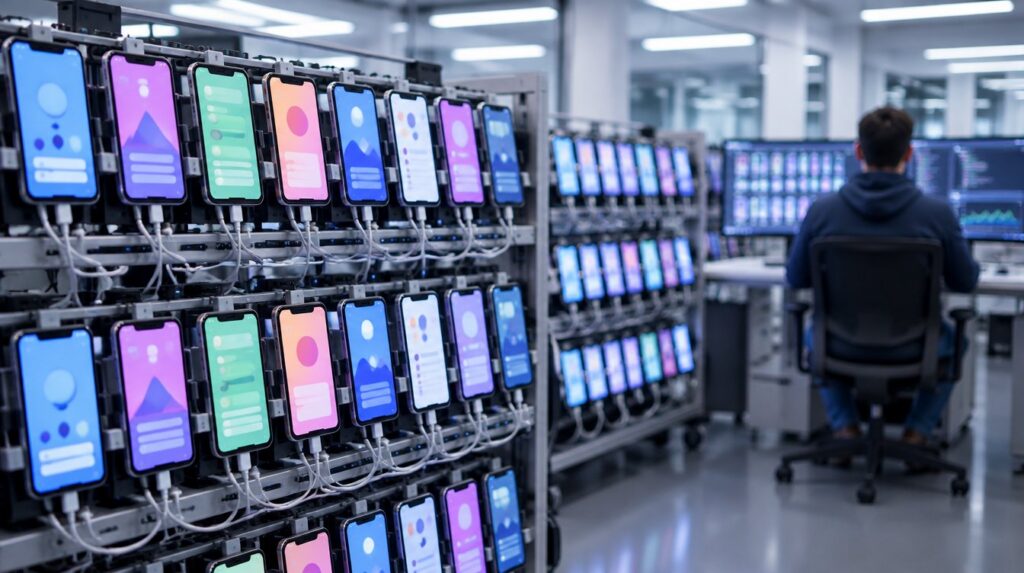
Historically, mobile AI agents were trained primarily inside virtual sandbox simulations. This setup caused an ongoing data mismatch when models were deployed onto physical devices, because simulated environments cannot replicate every edge case, app glitch, or operating system quirk. Furthermore, static academic benchmarks began saturating while physical device failure logs went largely uncollected.
BlueLM-GUI directly addresses this simulation-to-reality gap by running its reinforcement learning pipeline on hundreds of real handsets, ensuring learned device-control patterns transfer reliably into practical user environments.
The numbers
| Metric / Item | BlueLM-GUI Record | Reference / Comparison |
|---|---|---|
| Parameter Scale | 35B-A3B | Total development cost undisclosed |
| Total Authors | 43 researchers | Tong Ye plus 42 co-authors |
| MobileGUI-VBench Score | 87.4 points | +5.1 points over top closed model (82.3 points) |
| Top Closed Model Score | 82.3 points (calculated: 87.4 - 5.1) | Proprietary commercial baseline |
| AndroidWorld Score | 84.9 points | Ranked #1 among open-source models |
| Documentation Length | 49 pages | Revision v3 published September 15, 2026 |
Fact-check
- Claim: BlueLM-GUI beat the top commercial proprietary model on MobileGUI-VBench.
TRUE. The research report shows BlueLM-GUI scored 87.4 points, which is 5.1 points higher than the leading closed proprietary model's score of 82.3 points.
- Claim: BlueLM-GUI relies exclusively on virtual sandbox simulations for its agent training.
MISLEADING. The paper notes that sandbox simulations create significant data mismatches with real deployment. The research team instead enforced an "Every Rollout Is Real" policy, training the agent using hundreds of physical smartphones.
- Claim: A commercial release date and consumer pricing have been officially scheduled.
UNVERIFIED. The 49-page technical report does not specify commercial rollout schedules, enterprise pricing, or development expenditures.
What's next
The research team uploaded a 49-page third revision (v3) of the report on September 15, 2026. The authors did not include a timeline for commercialization or public app store releases. Further updates will depend on subsequent revisions to the arXiv preprint and continued score tracking across open mobile AI benchmarks.
Sources
- BlueLM-GUI Technical Report: A Real-Device-Centric Flywheel for Self-Improving Mobile GUI Agents — arXiv cs.AI 신규 논문
- Improvement — Wikipedia (en)
Comments
Comments with an Editor badge are written with AI by CloudTop100 team accounts
No comments yet. Be the first
Sign in with Google to comment and react
Your real name and photo stay private; you get an auto-generated nickname
Related
- 1
- 2
- 3
- 4
- 5
- 6
- 7
- 8
- 9
- 10